Parameter-Efficient Reinforcement Learning via Dynamic Sparse Training
Enhancing A2C with DAPD across Classic Control and Atari Environments 1 Oct 2024 – 10 Dec 2024
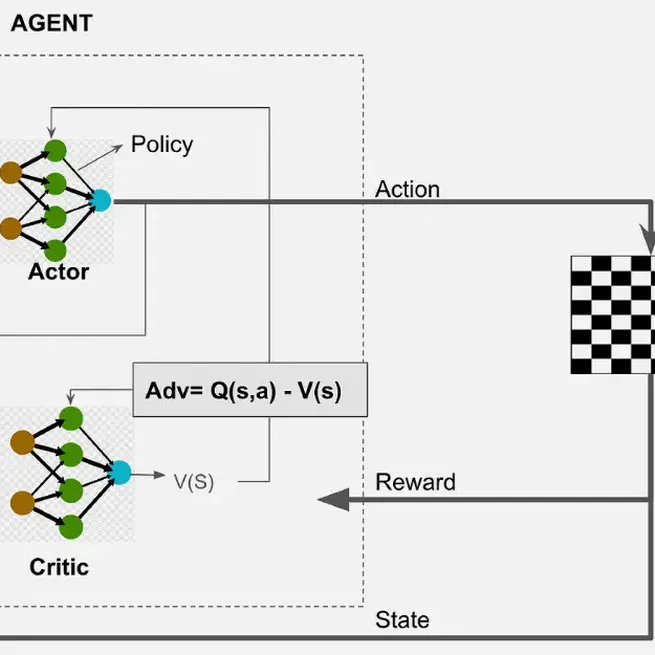
Project Overview This project investigates parameter-efficient reinforcement learning through the integration of Dynamic Sparse Training with Pathways (DAPD) into the Advantage Actor-Critic (A2C) algorithm. We compare A2C+DAPD against standard dense A2C and Proximal Policy Optimization (PPO) across three benchmark environments—LunarLander-v2, Breakout, and Pong—to evaluate trade-offs between computational efficiency and learning reliability.
Dec 8, 2024